


Technical SEO
Technical SEO, from analysis to technical implementation
A technical SEO report is worth little if the recommendations are then left untouched. I find out why search engines are not crawling, rendering or indexing your pages properly, decide what needs to happen first and adjust the code, the CMS or the configuration myself. Then I test again.
- SEO + development
- WordPress
- React & Next.js
- Work directly with Dries
At a glance
What is technical SEO?
Technical SEO ensures that search engines can find, crawl, render, understand and correctly index the pages of a website. It is not about what is on a page, but about the conditions for being read: the site architecture, HTTP status codes, canonicals, redirects, robots rules, XML sitemaps, JavaScript rendering, structured data and performance. Without that foundation, good content does not reach its audience: not in Google, and not in AI answers either.
I am a developer and an SEO consultant, and I work in WordPress, React, Next.js and Node.js. At MadeByDries, technical SEO does not stop at a report: where agreed, I also carry out the technical changes myself.
When
When do you need technical SEO?
When your website does something technical that hinders search engines, often without you noticing it on the front end. These are typical signs.
- Pages are not being indexed Search Console reports URLs that have been discovered or crawled, but not indexed.
- Rankings disappear after a redesign URLs, redirects or content have changed without search engines being able to follow.
- Google crawls the wrong URLs Parameters, filters or test environments get the attention your key pages need.
- Pages are treated as duplicates The same content can be reached via multiple URLs, or canonicals point to the wrong place.
- Redirect chains and loops Old URLs redirect in several steps, or lead nowhere.
- Slow pages and weak Core Web Vitals The most important content loads late, or the layout shifts.
- JavaScript content is missing for crawlers What a visitor sees is not in the HTML a crawler receives.
- Incorrect robots or noindex rules A setting left over from the test phase blocks pages that need to be live.
- A cluttered sitemap The sitemap contains URLs that redirect, do not exist or are set to noindex.
- Many 404 and 5xx errors Visitors and crawlers get stuck on pages or on the server.
- Errors in structured data or hreflang Markup does not match the page, or language versions do not reference each other correctly.
- Online shop filters create thousands of URLs Every combination of filters produces a new, almost identical page.
The journey
From URL to search result
Before a page appears in the search results, it goes through six steps. Technical SEO checks each step for problems.
- 1
Discover
Google finds the URL through a link or through the sitemap.
- 2
Crawl
Googlebot requests the URL and receives a status code.
- 3
Render
HTML, CSS and JavaScript are processed into the page a visitor sees.
- 4
Understand
Content, links, structure and structured data are interpreted.
- 5
Index
Google decides whether the page is stored, and which version.
- 6
Serve
The page can appear for search queries it matches.
A technical problem can block visibility at any of these levels. The diagnosis therefore starts with one question: at which step does it go wrong?
Indexing
Why is a page not indexed?
A page is not indexed when Google is not allowed to include it, cannot reach it or does not consider it worth storing. The first two are technical causes and can usually be pinpointed. The third is about content and internal priority.
- Noindex A meta tag or header explicitly asks for the page not to be indexed.
- Robots.txt The crawler is not allowed to request the URL and therefore does not see the content.
- Incorrect canonical The page points to another URL as the preferred version.
- Duplicate content Google chooses another URL with the same content.
- Soft 404 The page returns status 200 but looks empty or like an error page.
- Redirect The URL redirects: the destination is evaluated, not the URL itself.
- Server problems Timeouts or 5xx errors during crawling.
- JavaScript rendering The content only appears after scripts that the crawler does not run, or runs too late.
- Weak internal links Few or no links to the page, making it seem unimportant.
- Sitemap error The URL is missing from the sitemap, or is listed in a different form.
- Little unique value Content that hardly differs from other pages.
I determine which cause applies from Search Console, the raw HTML and the server responses, not from a hunch. Each cause is explained separately in Website or page not indexed?
Canonicals
Canonicals: which URL is the real version?
A canonical indicates which URL you intend as the preferred version when the same or nearly the same content is available via multiple URLs. Google treats the canonical as a strong signal, not a directive: if internal links, redirects or the sitemap contradict it, Google may choose a different URL. That is also what it says in Google’s documentation on canonical URLs.
That is why I check not just the tag, but whether all signals point to the same URL. Duplicate versions usually arise in these places. More in the canonical tag explained.
- Parameters
- Filters
- Sorting
- Product variants
- Tracking parameters
- www and non-www
- HTTP and HTTPS
- Pagination
- Language and country versions
Status codes
Status codes and redirects: what your server responds
Every request gets a status code in return. It tells a crawler whether the page exists, has moved or is missing.
The impact rarely lies in a single code, but in patterns: internal links pointing to redirects, redirect chains of three or four steps, loops, and status codes that do not reflect what is really going on. In a migration, those patterns decide whether your visibility moves with you. Guidance on that is covered on the page about website migration.
| Code | Meaning and what to watch |
|---|---|
| 200 | The page exists and is delivered. Watch out for pages that return 200 but are actually empty or show an error. |
| 301 | Permanent redirect. The right choice when a URL moves for good. |
| 302 | Temporary redirect. Often used by mistake where a 301 was intended. |
| 404 | The page does not exist. Normal for removed content, a problem when internal links point to it. |
| 410 | Deliberately and permanently removed. |
| 5xx | The server cannot handle the request. If it happens repeatedly, Google slows down its crawling. |
Robots and sitemaps
Robots.txt, noindex and XML sitemaps each do something different
Three tools that are often confused, leading to errors.
Controls crawling
robots.txt
Determines which URLs a crawler may request. A blocked URL can still be in the index if links point to it.
Controls indexing
noindex
Asks for a page not to be indexed. The crawler must be able to request the page to see that instruction.
Helps with discovery
XML sitemap
A list of the URLs you want indexed. It guarantees nothing, but shows what you consider important.
So if you want an existing URL removed from Google, use noindex or delete the page, and do not block it in robots.txt: otherwise Google can no longer read the noindex.
JavaScript SEO
JavaScript SEO: visible to users and crawlers alike
JavaScript sites need extra attention to rendering, crawlability and the HTML a crawler actually receives. Google can run JavaScript, but does so in a separate step and not always immediately: see Google’s JavaScript SEO basics guide. Other crawlers, including those of AI systems, often do not run scripts at all.
Client-side rendering
The browser builds the page with JavaScript. The initial HTML is almost empty: anything that does not run scripts sees nothing.
Server-side rendering
The server sends complete HTML for each request. Content, links and metadata are readable straight away.
Static generation
The HTML is built in advance. Fast and fully readable, suitable for content that does not differ per visitor.
That is why server-side rendering or prerendering is often useful for pages that need to be found. In React and Next.js, I decide per route which approach fits, and I check what is actually in the initial HTML. These are the points where things often go wrong.
- Hydration
- Deferred content
- Links without href
- Metadata per route
- Canonicals
- Status codes for client-side routes
WordPress
Technical SEO in WordPress
WordPress is a solid foundation for SEO. The technical problems usually arise from what is added on top: themes, page builders and plugins that each make their own choices.
I build WordPress websites myself and know both sides: what a plugin sets up well, and what is better solved in the theme or with a hook.
- Plugin conflicts
- Page builder output
- Duplicate archives
- Tags and categories
- Attachment pages
- URL parameters
- Canonical settings
- Cluttered sitemaps
- Caching
- Heavy scripts
- Images
- Redirects
- Schema from multiple plugins
Performance
Performance you can measure
Google measures user experience with three Core Web Vitals, based on real visits. The definitions are on web.dev.
LCP
Largest Contentful Paint
How quickly the main content of the page becomes visible.
INP
Interaction to Next Paint
How quickly the page responds when someone clicks, taps or types.
CLS
Cumulative Layout Shift
How stable the layout remains while the page loads.
A Lighthouse score of 100 is no guarantee of high rankings: Lighthouse is a lab test on a single device. Performance is one part of user experience, technical quality and SEO. I improve it where visitors and measurements are genuinely affected: images, scripts, fonts, server response time and caching. More in Core Web Vitals explained.
Structured data
Structured data: adding context, not a ranking hack
Structured data describes, in a fixed, machine-readable format, what is on a page: who the author is, which service is offered and where the page sits within the website. It is context, not a ranking hack. Markup must match what a visitor sees on the page.
The same applies to GEO (Generative Engine Optimization): machines understand the relationships between entities better when the website and the markup say the same thing. More in structured data and schema markup.
- Person
- Organization
- Service
- Product
- Article
- BreadcrumbList
What I do not do
- mark up invented reviews or ratings
- add an Offer without a real price or a real offer
- add schema solely to force a rich result
- use FAQ markup where the questions are not on the page
Structure
Technical SEO lives in the structure too
How pages link together determines what a crawler finds and how important it judges each page to be.
If you are building a new website, I define that structure before the design: see website development.
- Logical URLs Readable, stable and free of unnecessary parameters.
- Click depth Important pages are only a few clicks from the home page.
- Orphan pages Pages without internal links are rarely found.
- Internal links Ordinary links with an href and anchor text that says where they lead.
- Taxonomy Categories and tags that do not overlap.
- Pagination Subsequent pages that remain reachable where needed.
- Faceted navigation Filters that do not generate an endless series of URLs.
- One main intent per URL So that pages do not compete with each other.
More complex websites
Multilingual websites and online shops: where technology matters most
Scope
What is the difference between an SEO audit and technical SEO?
An SEO audit maps out problems and priorities. Technical SEO is the broader work through which that technical foundation is examined, improved and checked. At MadeByDries, analysis and implementation can follow on from each other within the same project.
An audit is therefore the diagnosis. Technical SEO also covers the repair and the follow-up checks. You can read what the diagnosis covers under SEO audit.
Analysis and implementation
No SEO report left gathering dust in a folder
A crawler or SEO tool can produce dozens or hundreds of warnings. Not every warning has the same impact, and some have none at all. So the work does not start with the list, but with the question of what is really happening.
I measure, check what is really happening, determine the impact, set the order, carry out the changes where we agree and test again. These are examples of what I then adjust.
- Templates
- Metadata logic
- Canonical logic
- Redirects
- Sitemap filters
- Structured data
- Rendering
- Performance
- Internal link components
- WordPress hooks
- Metadata and rendering in Next.js
Priorities
Not every technical SEO error is equally important
I classify findings into three levels. Not on the basis of a tool score, but on what they block in your situation.
Level 1
Blocking
Visibility is impossible until this is resolved.
- key pages not indexable
- an incorrect noindex
- rendering that fails
- server problems
- an incorrect canonical on key pages
Level 2
High impact
Visibility leaks away or is diluted.
- redirect chains
- duplicate URLs
- a weak architecture
- crawl waste caused by filters
- serious performance problems
Level 3
Optimisation
Worthwhile, but not urgent.
- minor improvements to the markup
- cleaning up metadata
- non-critical warnings
The same warning can be blocking on one website and a minor issue on another. That assessment is made by a specialist in context, not by a score.
GEO
Technical SEO is also the foundation for GEO
AI systems need to be able to reach, read and understand your content and link it to the right entities, just like a search engine. Semantic HTML, server-rendered content where needed, structured data, correct canonicals, crawlability and a clear architecture form the same foundation for that.
You can read what else is needed for visibility in AI answers under GEO & AI SEO.
I determine which cause applies from Search Console, the raw HTML and the server responses, not from a hunch.
Projects
Projects with the technology built in
Two of my own platforms in React, which I develop myself. The case studies explain how rendering, language versions and structured data were set up.
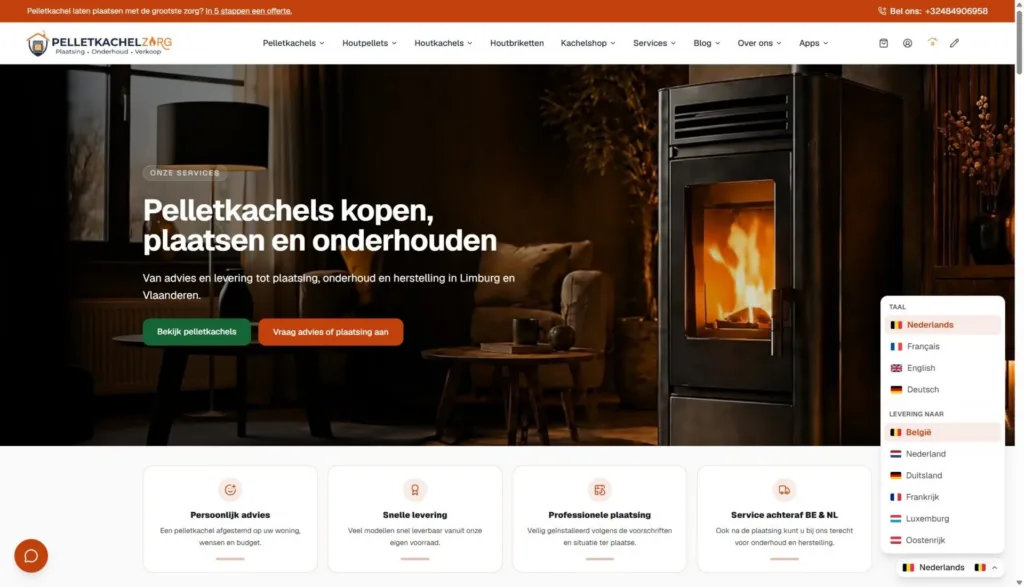
React & Next.js · E-commerce · Organic Web
Pelletkachelzorg
My own commerce platform in React and Next.js for the sale, installation and servicing of stoves, in four languages.
- React
- Next.js
- Claude
- GPT
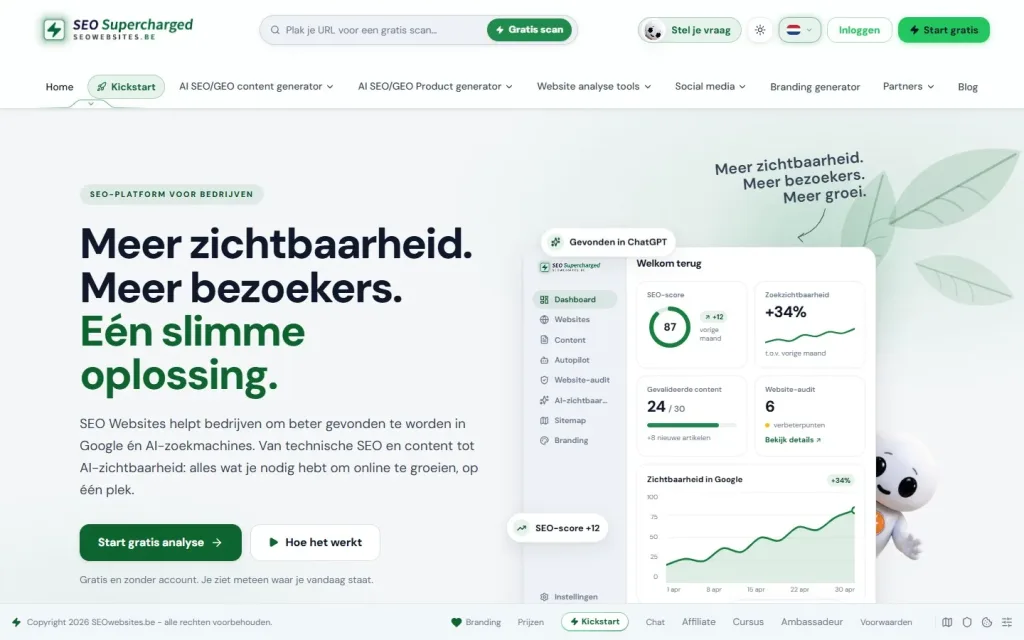
SEO · GEO · Organic Web
SEO Websites
My own SaaS platform for website analysis, SEO content and visibility in search engines and AI systems.
- React
- Node.js
- Express
- Claude
How I work
From technical problem to verified solution
As a defined assignment or as part of a broader SEO project. I do not promise a fixed turnaround time: it depends on the problem and on how quickly search engines process changes.
01
Diagnosis
What is really happening? Search Console, the raw HTML, the rendered page and the server responses side by side.
02
Impact
What affects crawlability, indexing or performance, and how severely?
03
Priority
What needs to happen first, what can wait and what is not needed.
04
Implementation
Changes to the code, the CMS or the configuration, made by me where agreed.
05
Validation
Recrawling, testing and checking that the change does what it should.
06
Monitoring
Following up on whether search engines process the change.
My measurement tools
I use server logs when they are available and relevant.
- Google Search Console
- Lighthouse and PageSpeed Insights
- Browser DevTools
- Crawlers
- DataForSEO
- Schema validators
Pricing
How much does technical SEO cost?
The price of technical SEO depends on the size of the problem and the work required to solve it. After an initial analysis, I can define the scope and price. It can be a one-off assignment: there is no mandatory monthly plan.
- Size of the website The number of pages and URLs involved.
- Platform WordPress, an online shop, React or Next.js, or bespoke development.
- Number of templates An error in one template affects every page that uses it.
- Type of problem Changing a setting is different from rebuilding the rendering.
- Technical debt What has been left undone over the years.
- Analysis or implementation Just the diagnosis, or the implementation as well.
- Complexity of the online shop Filters, variants and number of products.
- Migration A migration needs extra preparation and checks.
- Custom code How much existing code needs to be changed.
Why Dries
Technical SEO by someone who also builds
- Work directly with Dries You talk to the person who investigates and solves the problem.
- Developer and SEO consultant WordPress, React, Next.js and Node.js: I read the code where the problem lies.
- Analysis and implementation The recommendations are not left with a third party.
- With GEO in mind What I fix technically also helps AI systems read your content.

About the specialist
Dries Nijs, Organic Web Specialist
I am Dries Nijs, an Organic Web Specialist and technical SEO consultant from Maasmechelen. I have been building websites since the 1990s, today in WordPress, React, Next.js and Node.js. I use that development background not only to find technical SEO problems, but also to solve them. MadeByDries is the personal brand under which I work.
FAQ
Frequently asked questions about technical SEO
What does technical SEO cover?
Everything that determines whether search engines can find, crawl, render and index a website: site architecture, internal links, status codes and redirects, canonicals, robots rules, XML sitemaps, JavaScript rendering, structured data, hreflang and performance. The copy itself and links from other websites are not part of it.
What is the difference between technical SEO and regular SEO?
Technical SEO is one part of SEO. SEO also covers content (does a page answer the search query?) and authority (do other websites link to you?). Technical SEO makes sure content and authority can do their job. For the broader work, I am also available as an SEO consultant.
Why is Google not finding my website?
Usually for one of three reasons: Google cannot reach the pages, is not allowed to include them or does not find them distinctive enough. The first two are technical: a noindex, a block in robots.txt, an incorrect canonical, server errors or content that only appears via JavaScript. Search Console shows, for each URL, which reason Google gives.
How long does it take Google to index a page?
It varies from a few days to a few weeks, sometimes faster, and Google does not guarantee that a page will be indexed. It depends on how often your website is crawled, how the page is linked internally and how valuable Google considers it. A request via Search Console can speed it up, but cannot force it.
Is website speed important for SEO?
Yes, as one factor among many. Google uses the Core Web Vitals as a signal of user experience, but relevant content carries more weight. Speed matters most for your visitors: a slow page loses them before they have read anything. A perfect Lighthouse score is not a goal in itself.
What is a canonical tag?
A canonical tag is a line in a page’s HTML that indicates which URL is the preferred version when the same content is available via multiple URLs. Search engines use it as a strong signal to consolidate duplicate URLs, but are not obliged to follow it.
Is JavaScript bad for SEO?
No. JavaScript sites do need extra attention to rendering and to the HTML a crawler receives. With server-side rendering or static generation, as in Next.js, the content is in the HTML straight away. Problems arise when content, links or metadata only exist after scripts have run.
How do I know whether Google can crawl my website?
With the URL Inspection tool in Google Search Console, you can see for each page whether Google was able to fetch it, how it was rendered and whether it is indexed. The page indexing report shows this for the whole website. Also look at robots.txt, the status codes and what is in the raw HTML.
Is there a technical problem in your website?
Tell me what you see in Search Console or on your website. I will tell you what I can investigate and what I can fix myself.